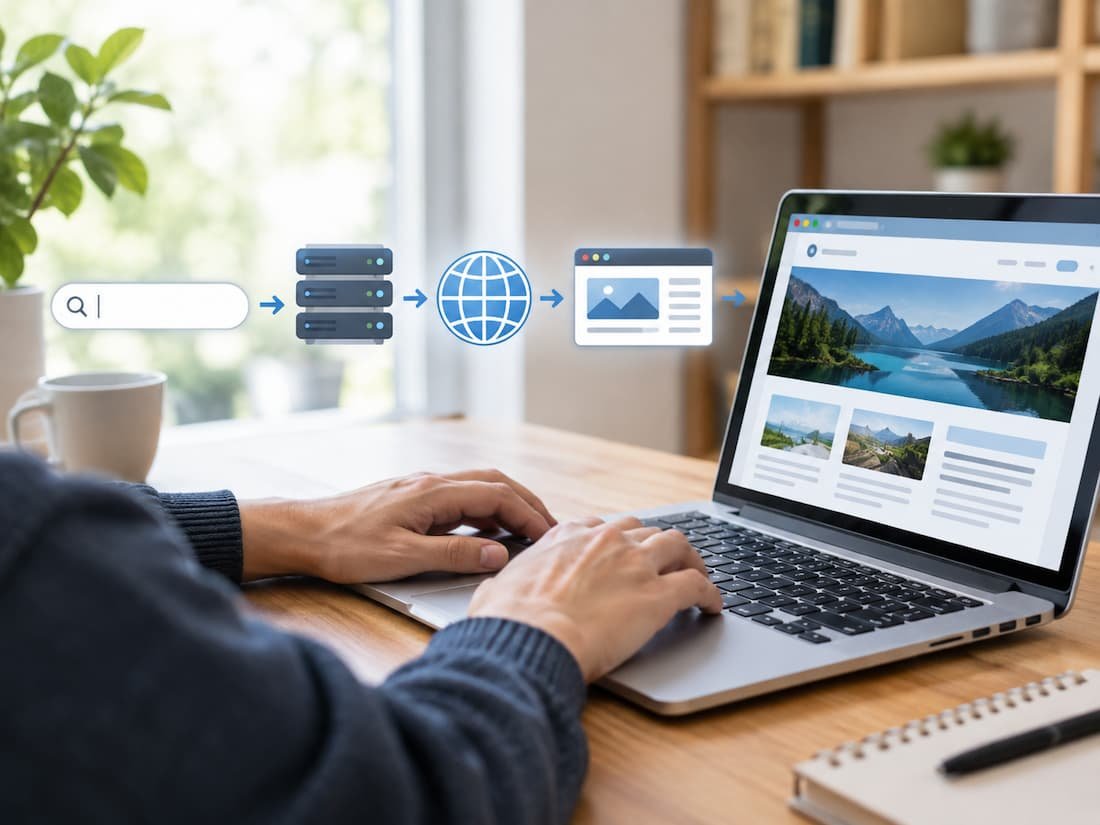
Most people experience the web as a single action: type a website name, press Enter, and a page appears. Technically, that action starts a chain of operations involving URL parsing, local caches, DNS resolution, IP routing, transport protocols, encryption, HTTP, servers, content delivery networks, and finally the browser’s rendering engine.
There is no single “website request” traveling directly from a browser to a server. First, the browser has to determine what resource is being requested and where it can be reached. The operating system and network may already know some of that information from previous activity. If they do not, additional network exchanges are required before the browser can even ask for the page.
The exact sequence also varies. Modern browsers may reuse connections, use cached resources, resolve DNS through encrypted DNS services, connect with IPv6 or IPv4, and negotiate HTTP/3 over QUIC instead of HTTP/2 over TCP. Understanding the normal path is therefore more useful than memorizing one fixed sequence.
It Starts With the URL, Not the Server
Suppose you enter https://www.example.com/products into the address bar. Before contacting the website, the browser interprets the URL.
The scheme, https, tells the browser that the resource should be accessed using HTTPS. The hostname is www.example.com. The path is /products. A URL can also contain a port, query parameters, and a fragment, each with a different role. The browser’s interpretation of these components determines which network protocol and destination it will use.
TechTalksX URL Component Analyzer
The browser may also decide that no network request is necessary. If the requested page or required resources are already available in an appropriate browser cache, some work can be satisfied locally. Other information, such as DNS results and previously established connections, may also be reusable.
This is one reason repeated visits to a website can behave very differently from the first visit. The visible action is identical, but the amount of work underneath it may not be.
DNS Turns the Name Into a Network Destination
A browser cannot send an IP packet to www.example.com simply because that text is meaningful to humans. It needs an address such as an IPv4 address or IPv6 address.
That is the job of the Domain Name System, or DNS.
DNS is distributed rather than being one enormous database stored on a single server. A resolver can use cached information, or it can follow the DNS hierarchy to obtain an answer. DNS records have a time-to-live (TTL), which tells caching systems how long particular information may be retained before it needs to be refreshed.
A simplified lookup might involve the following chain:
| Stage | System | Main role |
|---|---|---|
| 1 | Browser/OS | Check locally available information |
| 2 | Recursive resolver | Find or retrieve the requested DNS information |
| 3 | Root DNS | Direct the resolver toward the relevant top-level domain |
| 4 | TLD DNS | Direct the resolver toward the domain’s authoritative servers |
| 5 | Authoritative DNS | Provide the domain’s authoritative records |
| 6 | Recursive resolver | Return and cache the result |
In practice, many lookups stop much earlier because the recursive resolver already has a valid cached answer. The resolver’s cache is a fundamental performance mechanism: without caching, ordinary web browsing would require much more DNS traffic and additional network delay.
The result is not necessarily a single fixed web server. A domain can use DNS records to point toward different infrastructure, including addresses associated with load balancing or content delivery systems. The authoritative DNS configuration determines what information is returned; the browser then uses the resulting address to attempt a connection.
Modern DNS also does not have to travel as traditional unencrypted DNS traffic. DNS over TLS encrypts DNS communication using TLS, while DNS over HTTPS carries DNS queries and responses inside HTTPS exchanges.
You can inspect the kinds of records involved with a domain using the TechTalksX DNS Record Explorer.
An IP Address Still Does Not Tell the Browser Where the Page Is
Once the browser has an IP address, another misconception becomes important: the IP address does not mean the browser has established a direct physical connection to a particular computer.
The packet still has to travel through networks.
Your device sends traffic through its local network, typically toward a router or access point and then toward an Internet service provider. From there, routers forward packets through interconnected networks according to routing information. The precise path can change because Internet routing is distributed and dynamic.
At this stage, the information being moved is divided into packets rather than sent as one giant block representing the entire web page. Different layers of the networking stack handle addressing, transport, reliability where applicable, and application data.
This layered design is why the browser does not need to know which physical fiber-optic cables, routers, switches, or data-center links will carry every byte. It works with network protocols and endpoints while lower layers handle delivery across the network.
The Browser Then Establishes a Suitable Connection
After determining an address, the browser needs a transport and application protocol suitable for the request.
There are several possibilities. HTTP/1.1 and HTTP/2 commonly operate over TCP, while HTTP/3 operates over QUIC, which runs over UDP. HTTP/3 keeps the familiar HTTP request-and-response model but uses QUIC’s transport mechanisms underneath.
With TCP, establishing a new connection involves the well-known three-way handshake. The client and server exchange SYN and acknowledgment messages to synchronize their TCP sequence-number state before normal application data is exchanged.
HTTP/3 takes a different route. QUIC provides its own connection establishment and incorporates TLS 1.3 into the transport design. It also supports multiple independent streams within a connection, allowing separate exchanges to progress without requiring every stream to wait for another stream’s lost packet.
The browser and server therefore do not necessarily perform the same connection sequence every time. Existing connections can be reused, while HTTP/3-capable clients may establish QUIC connections when the necessary conditions are met. If QUIC connectivity fails, HTTP/3 specifies that clients should be able to fall back to TCP-based HTTP versions.
HTTPS Adds Authentication and Encryption
For an HTTPS website, establishing the transport connection is only part of the process. The browser also needs a secure cryptographic session.
TLS, or Transport Layer Security, performs a handshake in which the endpoints negotiate cryptographic parameters, establish shared keying material, and authenticate the server when certificate-based authentication is used. After the handshake, application traffic is protected using the resulting keys.
This is more than simply “encrypting the website.”
The server’s certificate provides an identity binding that the browser can validate against its trusted certificate infrastructure. The TLS handshake also establishes cryptographic keys used to protect the subsequent traffic. TLS 1.3 is designed to provide confidentiality and integrity for protected application data and to authenticate the communicating endpoint.
For HTTP/3, QUIC uses TLS 1.3 as its handshake protocol. The HTTP/3 specification also requires the client to communicate the target host during the TLS handshake, normally using Server Name Indication when the server is identified by a domain name.
That matters because one IP address can serve many domains. The network destination and the requested website name are related, but they are not necessarily the same piece of information.
The Browser Finally Sends an HTTP Request
Once the appropriate connection and security state are ready, the browser can send an HTTP request.
Conceptually, the request says which resource is wanted and includes metadata that helps the server process it. Depending on the request and protocol version, this can include information such as the HTTP method, requested path, accepted content types, compression capabilities, cookies, language preferences, and other headers.
The server does not necessarily respond with a finished page that contains everything the browser will display.
It may return an HTML document that references stylesheets, JavaScript files, images, fonts, videos, or additional data endpoints. The browser then discovers those dependencies while processing the response and may make many additional requests.
A redirect can add another stage. Instead of returning the requested document immediately, the server can return an HTTP redirect response telling the browser to request another URL. Status codes such as 301, 302, 307, and 308 have different defined semantics, so a redirect is not simply an informal instruction to “go somewhere else.”
TechTalksX HTTP Status Code Explorer
The Server May Not Be the Machine You Imagine
At this point, it is tempting to picture a browser communicating with one computer sitting in a data center. Modern websites are often more complicated.
A request may first reach a CDN edge location, reverse proxy, load balancer, web server, application server, cache, or some combination of these. A CDN can serve static content from an edge location instead of requiring every request to travel to an application’s origin infrastructure.
For dynamic requests, the infrastructure may then invoke application code, query databases, access object storage, call another service, or retrieve information from a cache. The exact architecture is application-specific. Public documentation can describe a provider’s products and protocols, but the internal architecture of a particular website may be proprietary and should not be assumed.
The important point is that an HTTP response represents the result of a larger processing system. The browser does not need to know whether that result came from a memory cache at an edge location or from application code that performed several backend operations.
Receiving HTML Is Only the Beginning
When the first HTML bytes arrive, the browser starts processing them. It does not necessarily wait for the entire page to download before doing useful work.
The HTML parser converts the incoming markup into a Document Object Model, or DOM. As the browser encounters references to external resources, it can initiate additional requests. CSS is parsed into a CSS Object Model, or CSSOM. The browser then combines the DOM and CSS information into the structures needed to determine what should be displayed.
JavaScript can complicate this process because scripts may inspect or modify the DOM, request additional data, change styles, and trigger further work. Some resources can therefore affect when particular parts of the page can be rendered.
This is why the amount of data downloaded is only one part of page-loading performance. Network latency, connection establishment, server processing, resource dependencies, JavaScript execution, layout, painting, and device performance can all contribute to what the user experiences.
From Render Tree to Pixels
After the browser has enough information to determine the structure and styles of visible content, it performs layout. Layout determines dimensions and positions. The browser then paints the visual elements and ultimately produces pixels that the operating system and graphics subsystem can display.
This sequence is commonly described as the critical rendering path. It involves parsing HTML, constructing the DOM, processing CSS, building the render tree, calculating layout, and painting.
The important distinction is that downloading a page and displaying a page are different operations.
A server can respond quickly while a complex page still requires substantial client-side processing. Conversely, a relatively large response can sometimes display efficiently when its resources are well organized and much of the content can be processed progressively.
What Can Make Two Page Loads Behave Differently?
There is no guaranteed fixed number of steps or network round trips for every visit. Several variables can change the path.
| Factor | What can change |
|---|---|
| DNS cache | A lookup may be answered locally or from a recursive resolver cache |
| Browser cache | Some resources may not need to be downloaded |
| Existing connection | TCP or QUIC setup may already have occurred |
| HTTP version | HTTP/1.1, HTTP/2, and HTTP/3 use different transport arrangements |
| IPv4/IPv6 | The client may have multiple possible network paths |
| CDN | Content may be served from infrastructure closer to the client |
| Redirects | The initial URL may lead to additional requests |
| Cookies/session state | The server may generate a different response |
| JavaScript | Client-side code can trigger additional requests and rendering work |
| Server load | Backend processing time can vary |
Caching is particularly important because it means “typing a website name” does not always mean starting from zero. DNS records, HTTP resources, connection state, and other information may be reusable under the relevant rules.
Why a Page Can Fail at Different Stages
This complete chain also explains why web problems can look deceptively similar.
If DNS resolution fails, the browser may never reach the destination server. If the network route fails, DNS may work perfectly while packets cannot reach the service. If TLS negotiation fails, the server may be reachable but the secure connection cannot be established. If the HTTP server returns an error, the network and TLS layers may have worked normally. If the HTML arrives but JavaScript fails, the server may have successfully delivered the page even though the application does not behave correctly.
The same visible symptom—”the website won’t load”—can therefore originate from completely different layers.
A slow first visit can also have a different cause from a slow page after the site has already loaded once. The first visit may require DNS resolution, connection establishment, TLS negotiation, and downloading resources that later visits can reuse or retrieve from cache.
The Web Page You See Is the Final Result of Several Systems
Typing a website name looks like a single request because the browser hides almost all of the intermediate machinery. Underneath, however, the process crosses several boundaries: a human-readable URL becomes a network destination; DNS maps names to address information; routers move packets between networks; TCP or QUIC provides transport; TLS establishes a protected session; HTTP transfers application resources; servers and infrastructure generate or retrieve those resources; and the browser converts the resulting bytes into pixels.
The useful lesson is not that every page load follows one rigid sequence. Modern web stacks deliberately allow several paths depending on caching, protocol support, network conditions, server configuration, and browser behavior. HTTP/3 may use QUIC, DNS may be obtained through encrypted mechanisms, and a CDN may answer a request before it reaches an origin application.
Once these layers are understood, everyday web behavior becomes easier to reason about. A DNS problem, connection problem, TLS problem, HTTP error, server delay, and browser rendering problem are no longer indistinguishable parts of “the Internet.” They are different stages of a larger pipeline, each with its own protocols, failure modes, and evidence.